Yuta Oshima
I’m a second-year Ph.D. student at the University of Tokyo, advised by Professor Yutaka Matsuo. I am also a research intern at Sakana AI and AIRoA.
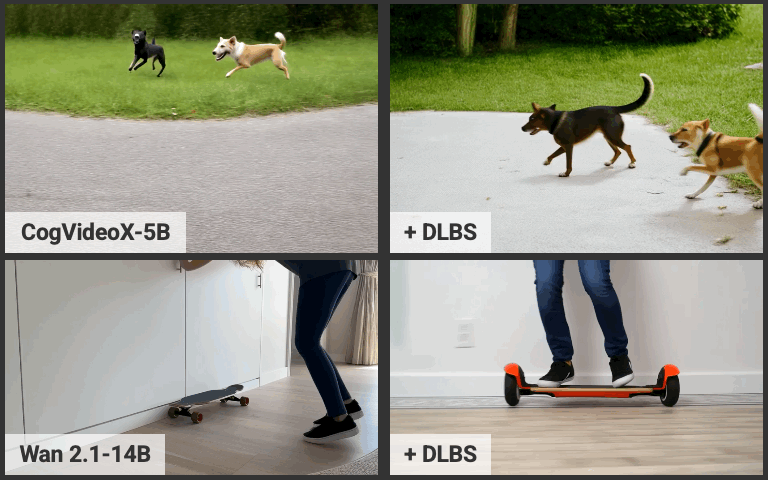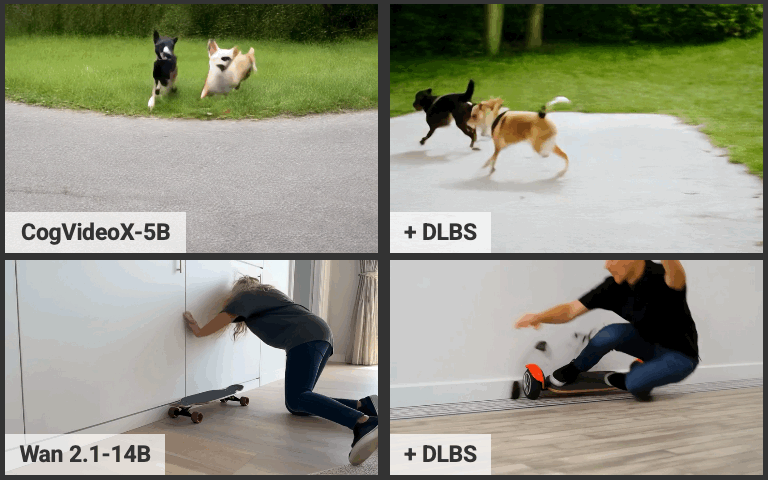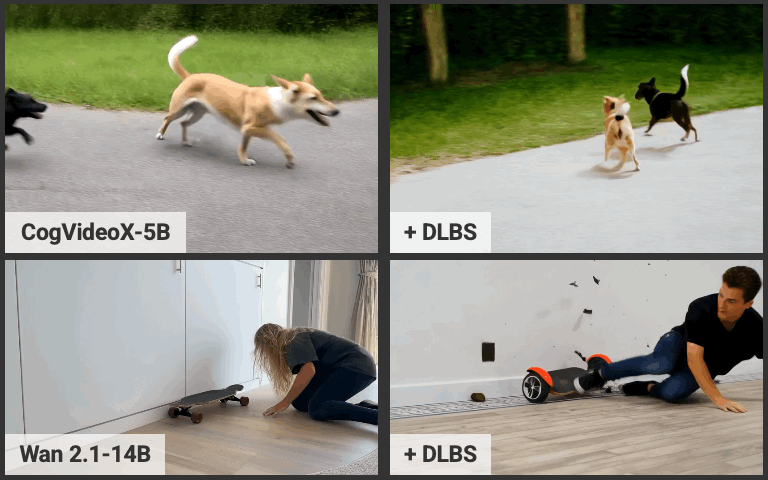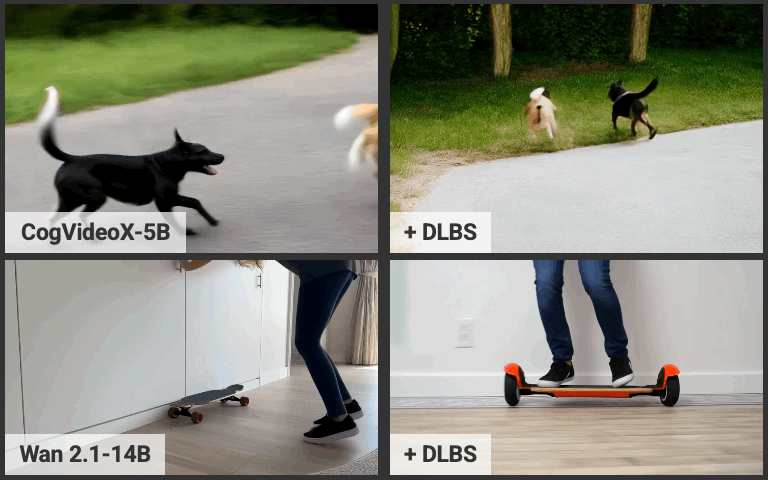
My Ph.D. research aims to unlock the potential of image and video generation AI and expand the domains where it can be used. Just as LLMs are now indispensable across countless domains, image and video generation should follow the same path. To this end, I am currently working on 𝗱𝗶𝗳𝗳𝘂𝘀𝗶𝗼𝗻 𝗺𝗼𝗱𝗲𝗹𝘀 for video generation and world models, and 𝗺𝘂𝗹𝘁𝗶𝗺𝗼𝗱𝗮𝗹 𝗔𝗜 𝗮𝗴𝗲𝗻𝘁𝘀 for image generation.
selected publications
- CVPR 2026 Main
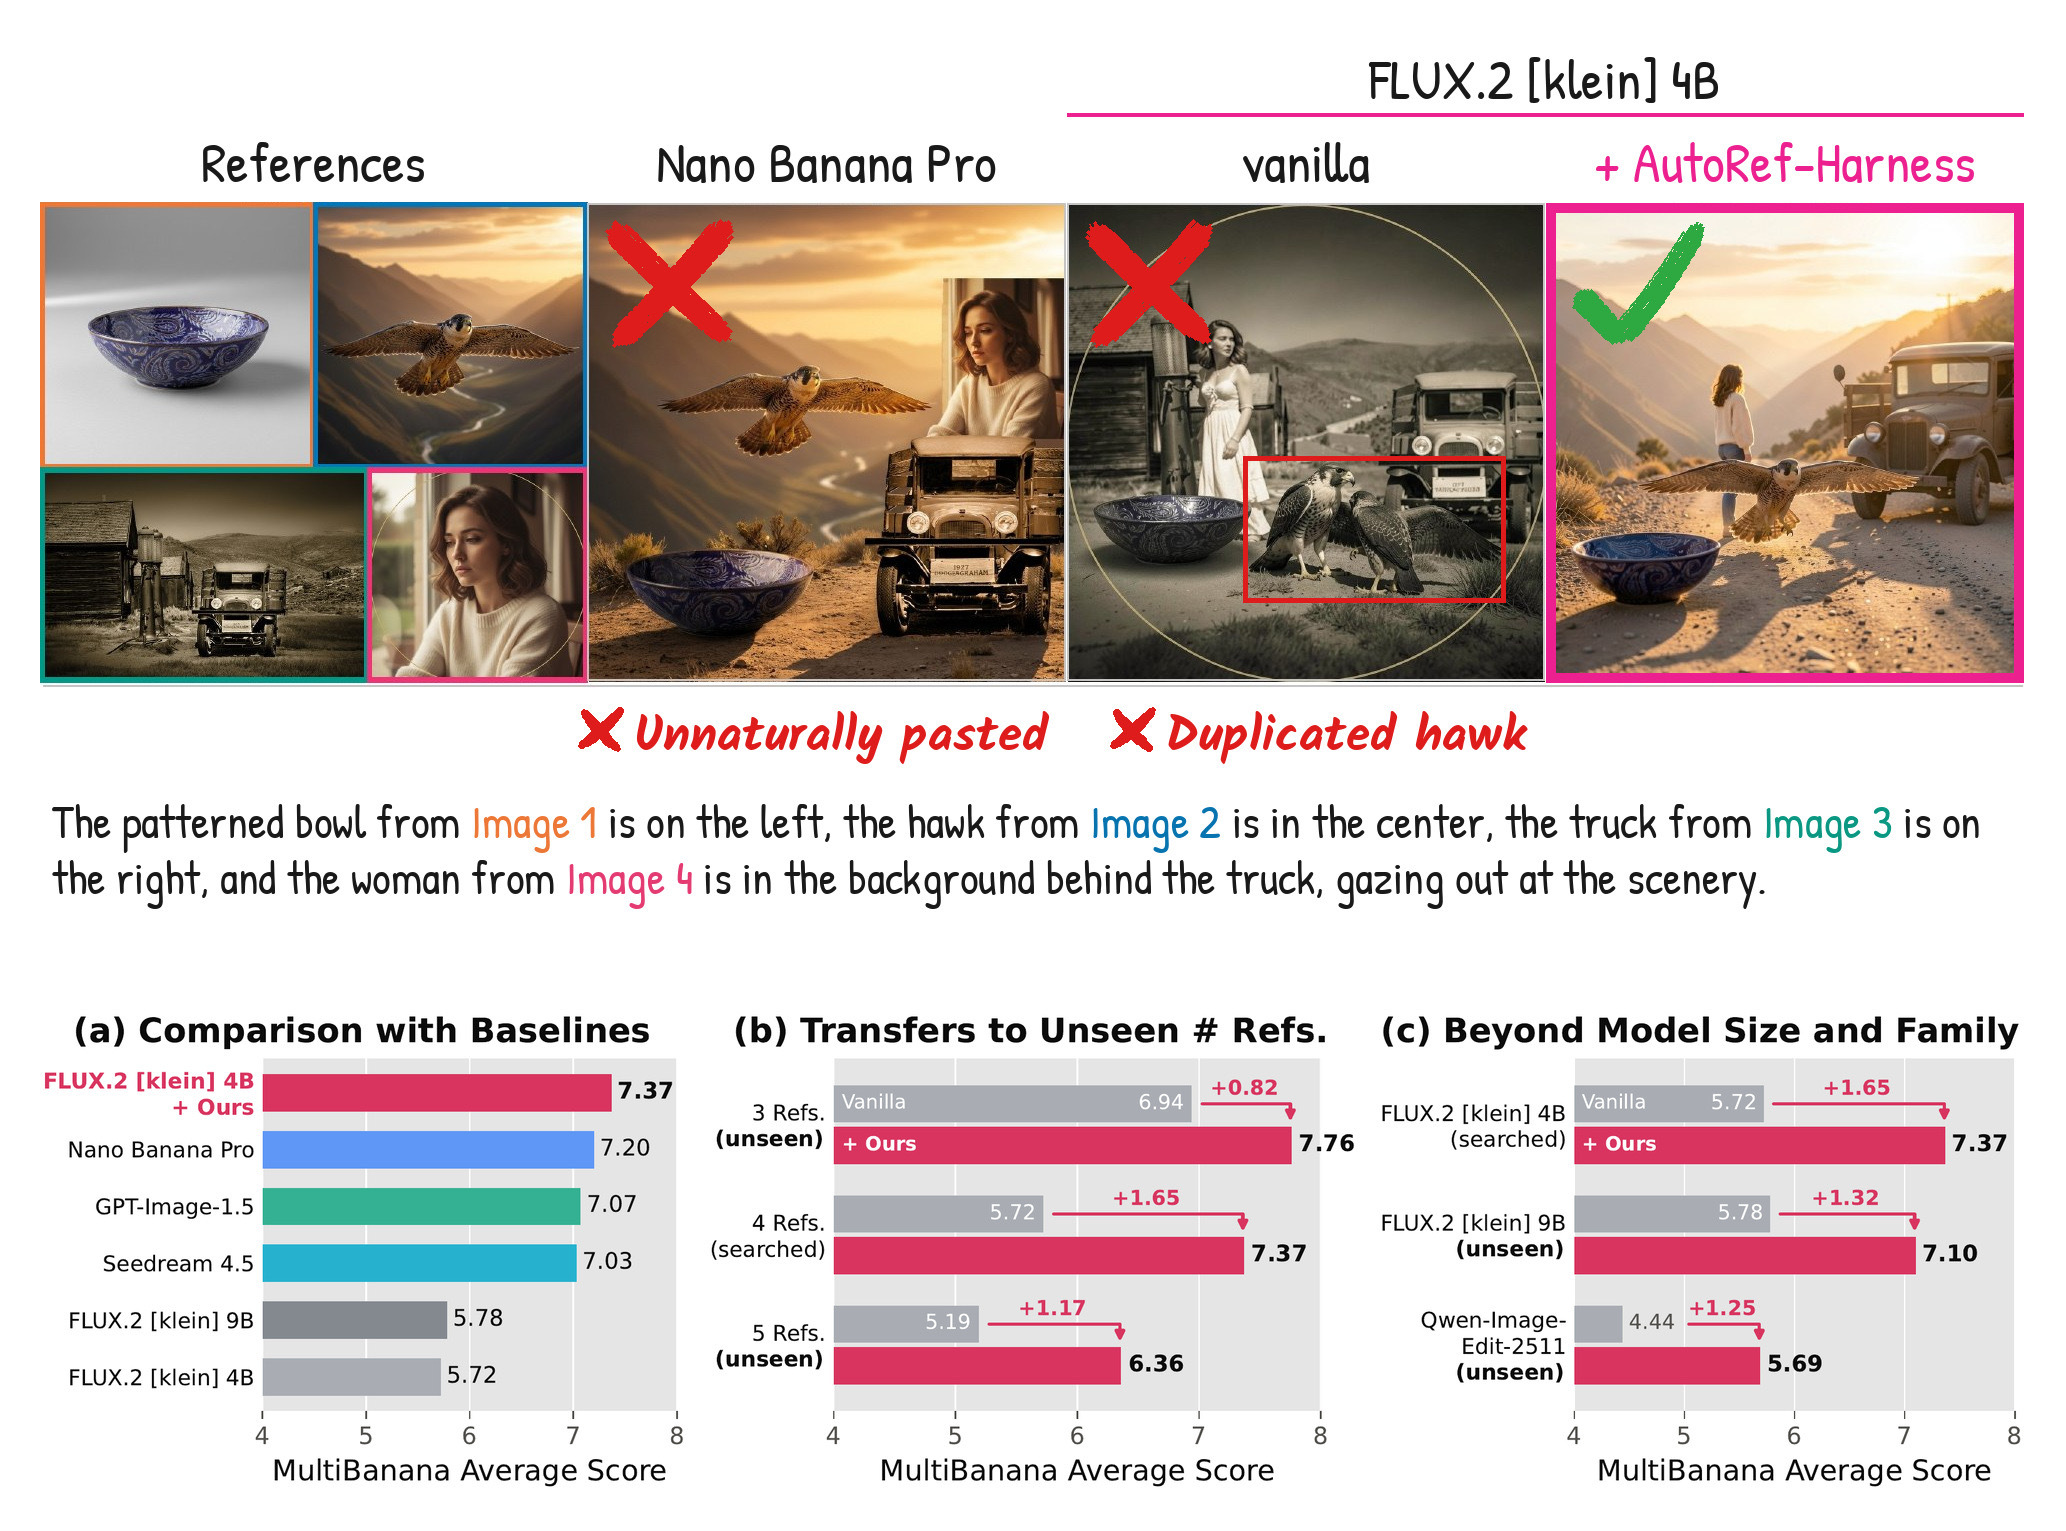
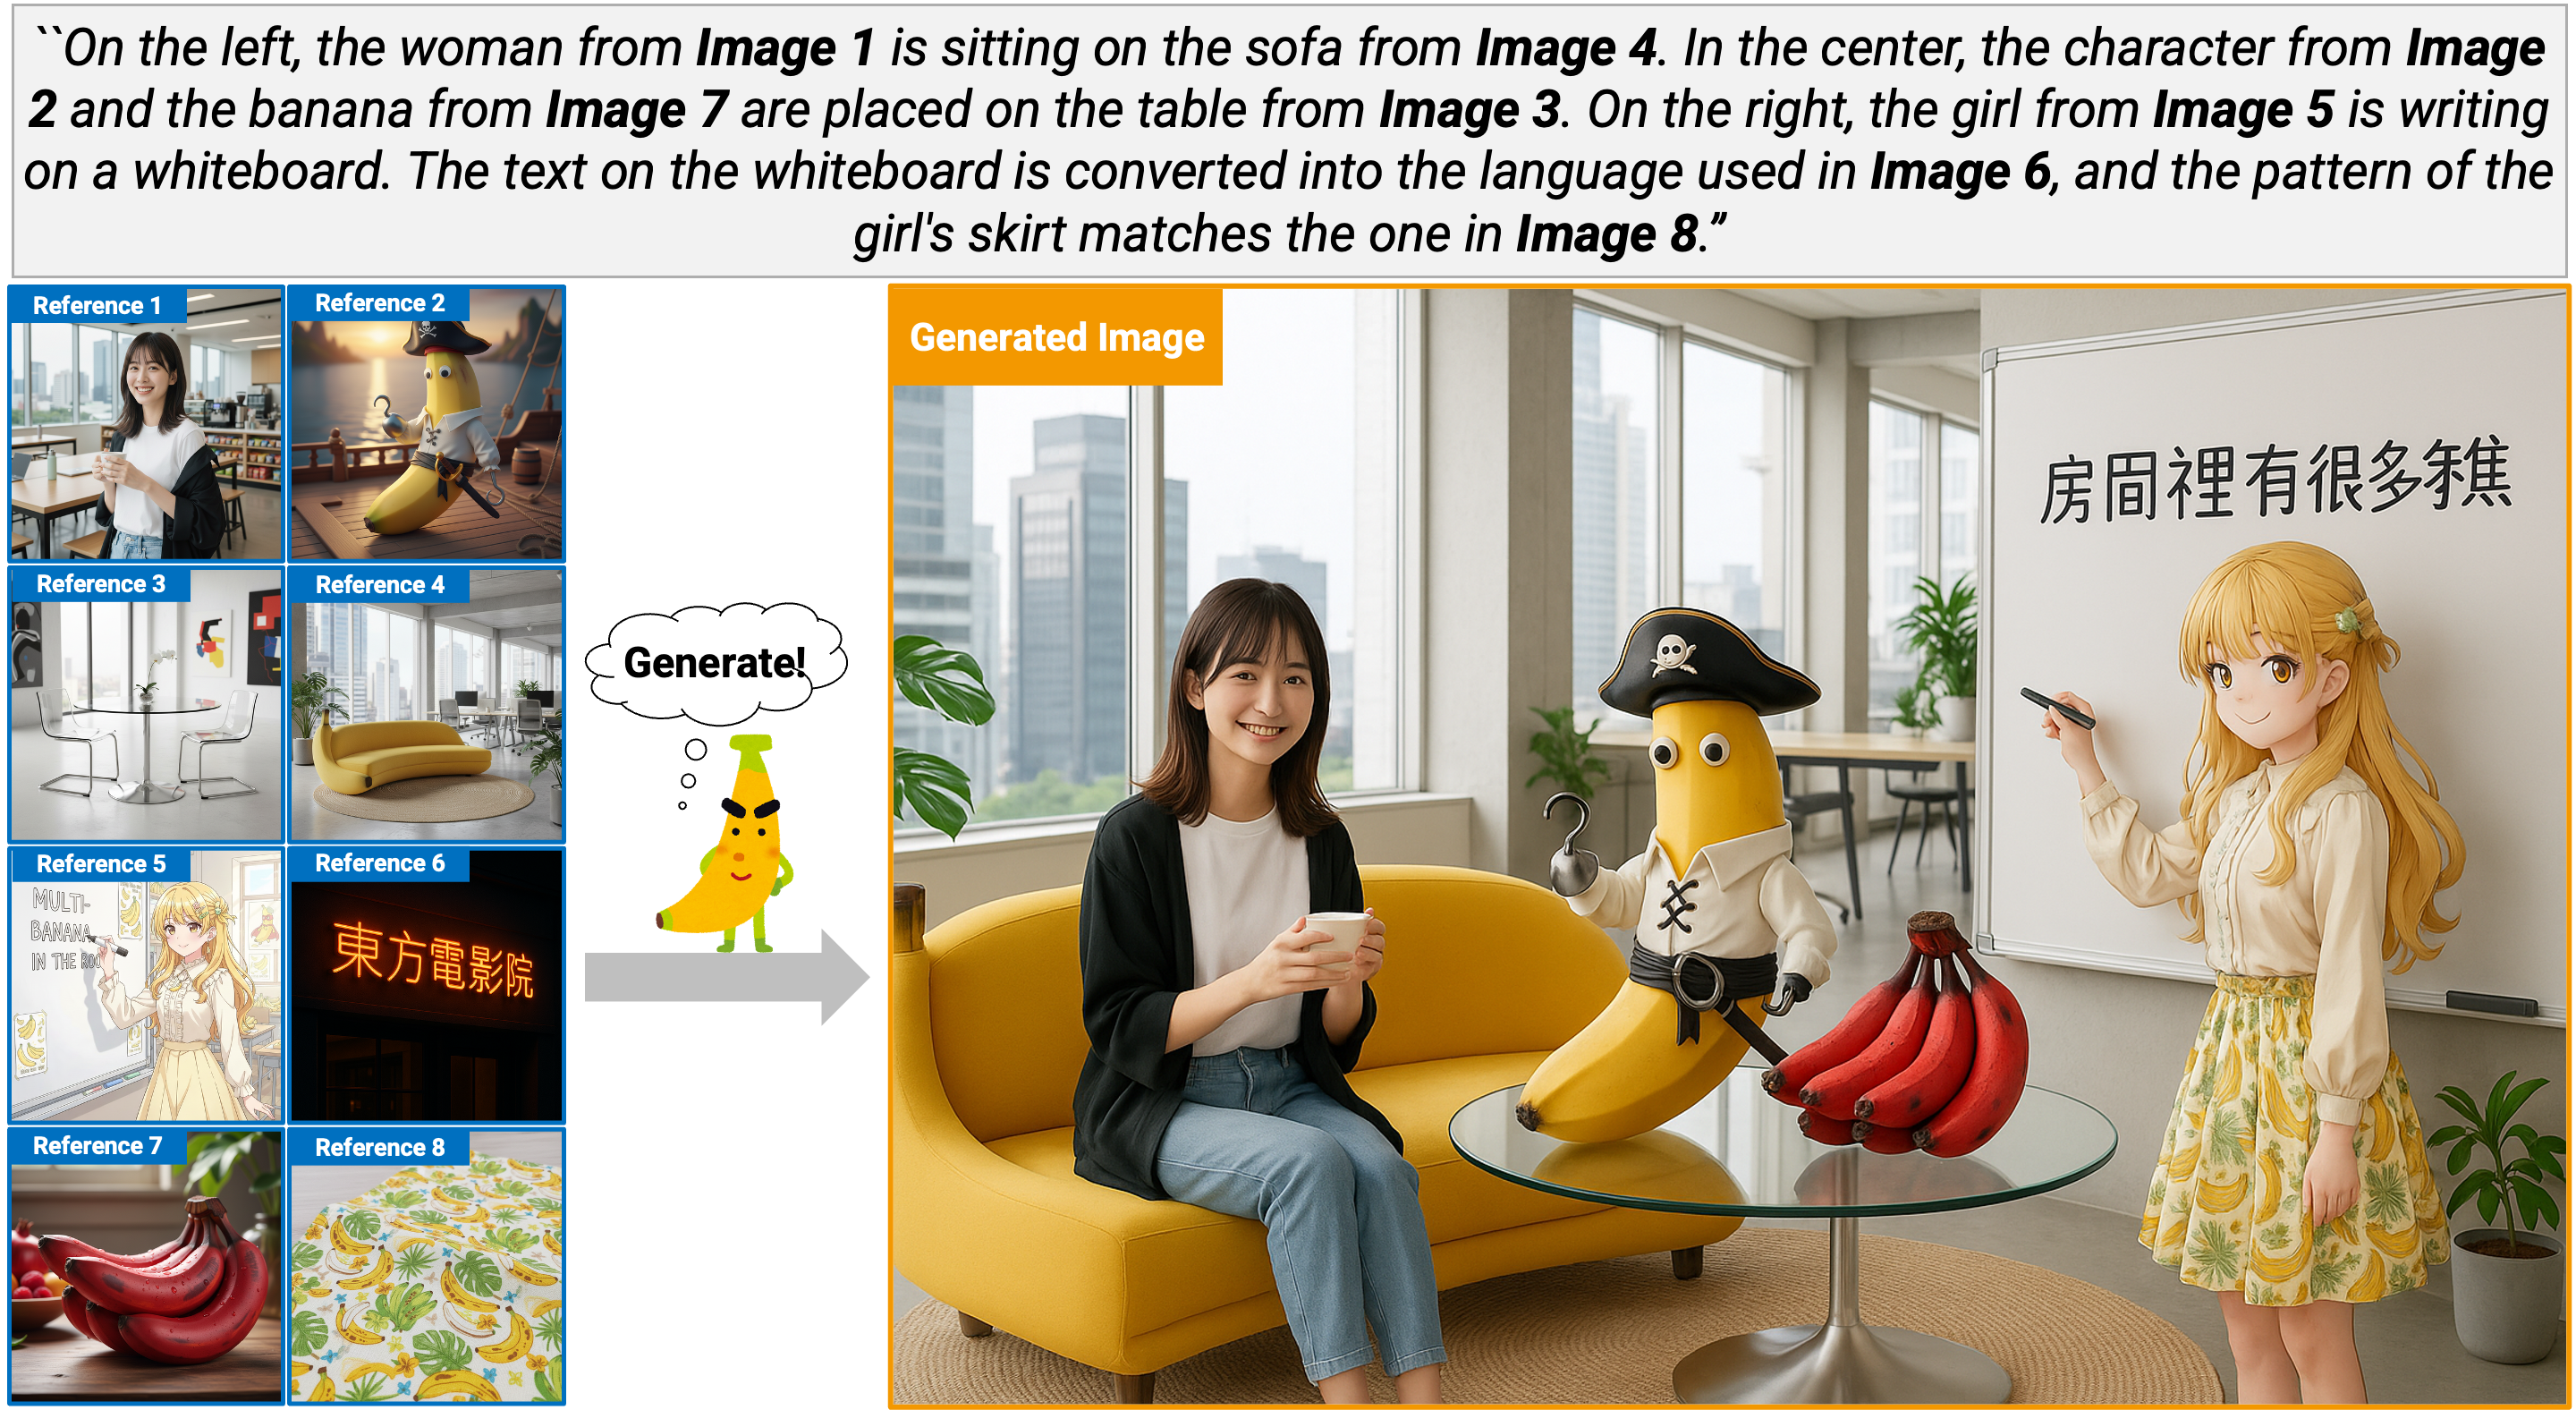 MultiBanana: A Challenging Benchmark for Multi-Reference Text-to-Image GenerationIn the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026
- TMLR 2026
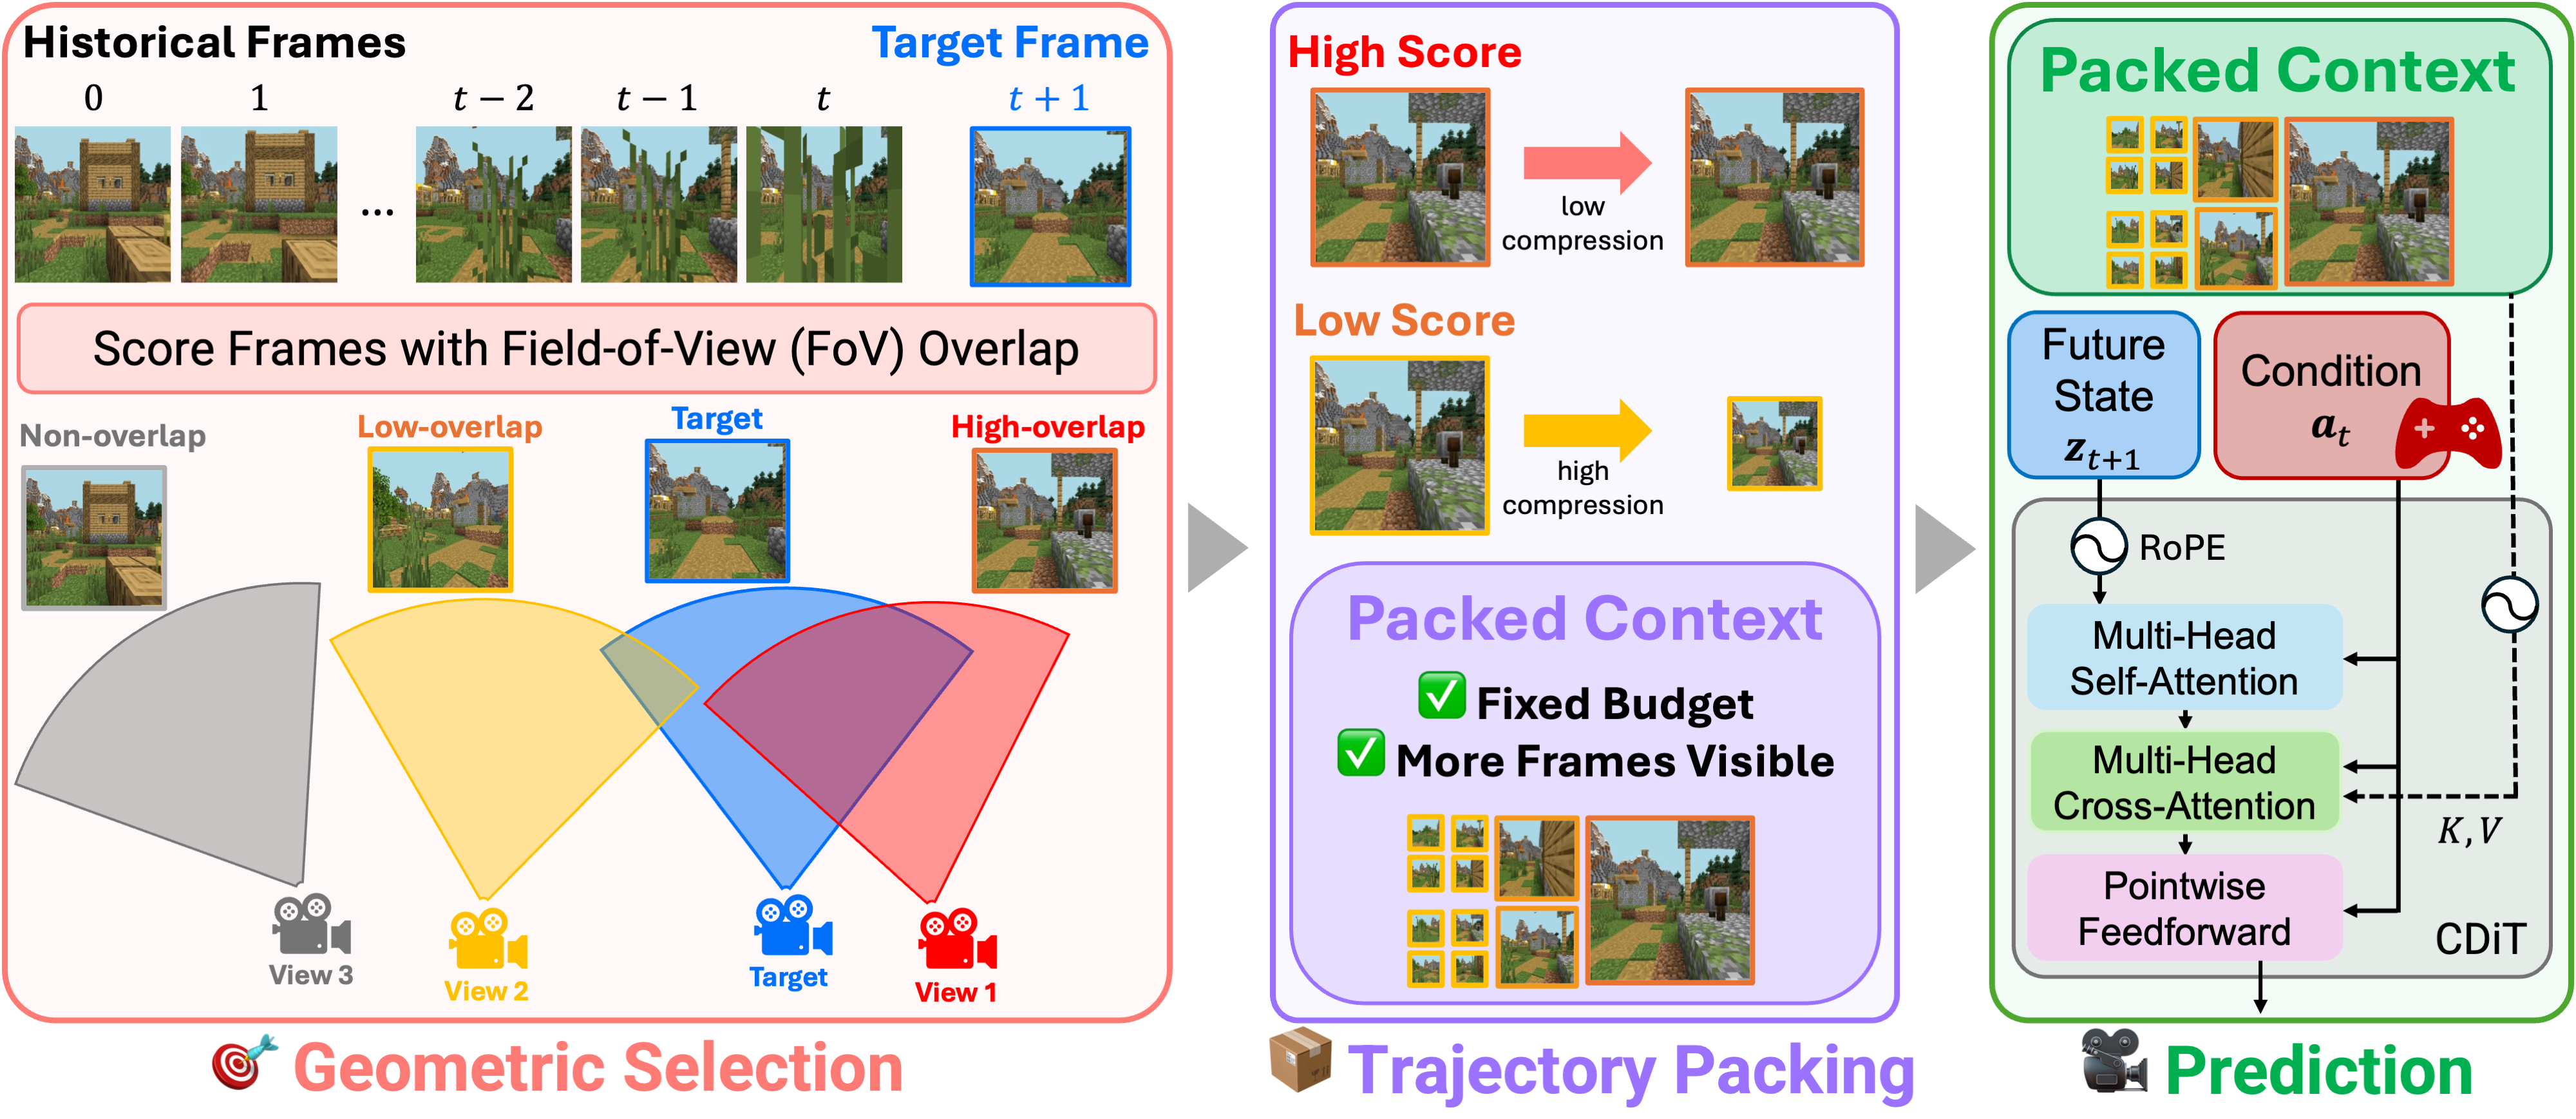 WorldPack: Dynamic Frame Compression for Long-context Video World ModelingIn Transactions on Machine Learning Research, 2026